A high star rating is a vanity metric if the underlying review ignores the specific constraints of your workflow. For SEO professionals and agency owners, a "4.5-star" rating on a SaaS tool or service is functionally useless without knowing if that score was dragged down by a poor UI or a fundamental failure in data accuracy. The current trend in review aggregation favors "sentiment smoothing"—a process where nuanced technical feedback is compressed into digestible, often misleading, bullet points. This lack of context doesn't just annoy readers; it leads to expensive procurement errors and inflated churn rates.
To make an informed buying decision, you need to look past the summarized consensus. Effective review summaries must bridge the gap between broad user satisfaction and specific technical requirements. When context is stripped away to favor a "clean" summary, the most critical data points—latency, API stability, and actual seat-based costs—are the first to disappear.
The Technical Cost of Sentiment Smoothing
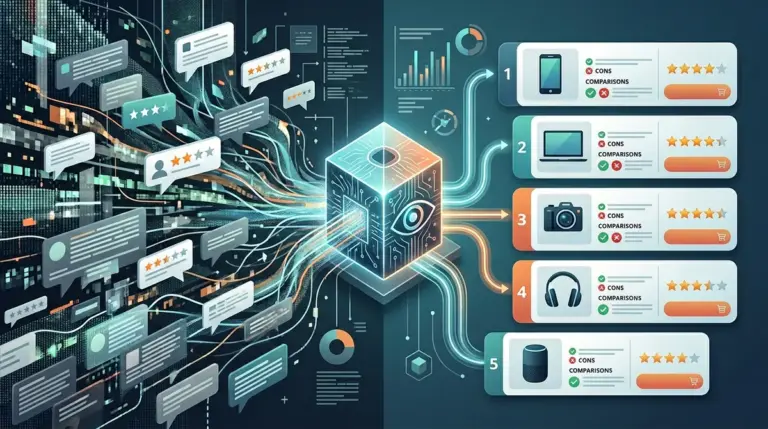
Most automated review summaries use Natural Language Processing (NLP) to categorize feedback into "Pros" and "Cons." While efficient, this method frequently strips away the "why" behind a user's frustration. For example, a summary might list "steep learning curve" as a con. For an enterprise agency with a dedicated training budget, this is a non-issue. However, for a solo consultant needing an immediate solution, it is a dealbreaker. Without the context of the reviewer’s team size and technical literacy, the summary provides no actionable value.
Spin enters the equation when summaries prioritize "positive sentiment" to maintain affiliate click-through rates. You will often see phrases like "robust reporting features" used to mask a lack of real-time data updates. A truly useful summary doesn't just list a feature; it defines the limitations of that feature. If a tool offers "unlimited reports" but throttles export speeds after the tenth download, a summary that only mentions "unlimited access" is technically accurate but commercially dishonest.
Decoding Marketing Spin in B2B Summaries
Identifying spin requires a sharp eye for "hollow adjectives." These are words that sound authoritative but lack a measurable baseline. When evaluating a review summary, look for specific differentiators rather than general praise. If a summary claims a platform is "fast," it should be supported by specific load times or sync frequencies. If it claims a service is "affordable," it must be compared against the industry average for that specific tier of service.
Best for: Identifying high-intent software reviews. Look for summaries that include version numbers, specific integration names (e.g., "native BigQuery connector" vs. "good integrations"), and specific use-case scenarios like "high-volume keyword clustering for e-commerce."
The Role of Edge Cases and Outliers
Marketing spin tends to average out the outliers. However, in the SEO and marketing world, the outliers often contain the most valuable information. A 1-star review from a user who tried to run 50,000 concurrent API calls tells you more about a tool's ceiling than twenty 5-star reviews from users who only check their dashboard once a week. A context-rich summary should highlight these "stress tests" rather than burying them under a general satisfaction score.
Data Points That Define Contextual Value
To move beyond spin, a review summary must address the specific friction points that affect ROI. When you are auditing a service or tool based on a summary, check for the presence of these five concrete factors:
- Implementation Velocity: How many days or weeks does it realistically take from purchase to a fully functional workflow?
- Integration Depth: Does the tool have a "shallow" integration (data visualization only) or a "deep" integration (two-way data syncing and automation triggers)?
- Hidden Overhead: Does the "starting price" include essential features like data exports, multi-user access, or priority support?
- Scalability Friction: At what point does the per-unit cost increase? Many tools are affordable for small datasets but become prohibitively expensive at the enterprise level.
- Support Accountability: Does the summary distinguish between "24/7 chat" (which might be a bot) and "dedicated account management"?
Warning: Be wary of summaries that rely heavily on "user-voted" pros and cons. These are often skewed by users who have only spent a few hours with a product. A summary that doesn't weight the feedback of long-term power users against trial-phase users will always lean toward superficiality.
How to Write Summaries That Build Authority
If you are producing reviews for an audience of professionals, your summaries must prioritize utility over brevity. The goal is to save the reader time, not just to give them a "yes/no" answer. This requires a structural shift in how information is presented. Instead of a list of features, use a "Scenario-Outcome" framework. For example, instead of saying "The tool has good data filtering," write "The multi-layer filtering allows for sub-niche analysis in under 30 seconds, making it ideal for large-scale site audits."
This approach forces the writer to provide context. It moves the conversation from "Is this tool good?" to "Is this tool good for this specific task?" For an SEO agency, the difference between those two questions represents thousands of dollars in annual software spend. Contextual summaries also perform better in search because they naturally include the long-tail, problem-aware keywords that high-intent buyers actually use when they are close to a purchasing decision.
Optimizing for Trust Over Volume
The transition from spin-heavy summaries to context-driven analysis requires a commitment to transparency. This means acknowledging where a product fails just as clearly as where it succeeds. For publishers, this builds long-term brand equity. A reader who avoids a bad purchase because of your honest summary is more likely to return to your site when they are ready to buy a different solution. In the current SEO climate, where "Helpful Content" is a primary ranking factor, providing this level of granular, honest detail is no longer optional—it is a competitive necessity.
Frequently Asked Questions
How can I tell if a review summary is AI-generated without human oversight?
Look for repetitive sentence structures and a lack of specific versioning or date-sensitive data. AI summaries often hallucinate features that were deprecated or fail to mention recent UI overhauls. If the summary uses vague terms like "game-changer" or "seamless experience" more than twice, it likely lacks human editorial vetting.
Why are negative reviews sometimes omitted from summaries?
This is often a result of "sentiment weighting" where a high volume of short, positive reviews (often incentivized by the vendor) outweighs a few detailed, negative technical critiques. To find the truth, look for summaries that specifically mention "Common Criticisms" or "Limitations" as a dedicated section rather than a single bullet point.
Does more context always mean a longer summary?
Not necessarily. Context is about density, not length. A 200-word summary that details API rate limits and seat-based pricing is more contextual than a 1,000-word summary that uses flowery language to describe the user interface. Focus on "data density"—the ratio of facts to adjectives.
How should I use review summaries in my procurement process?
Use the summary to narrow your shortlist to three candidates, then ignore the summaries and read the raw 3-star and 4-star reviews for those specific tools. These "middle-ground" reviews are usually where the most honest technical context lives, as they aren't written by angry outliers or brand evangelists.